ChatGPT Audio Transcription Checklist for Fast Accuracy
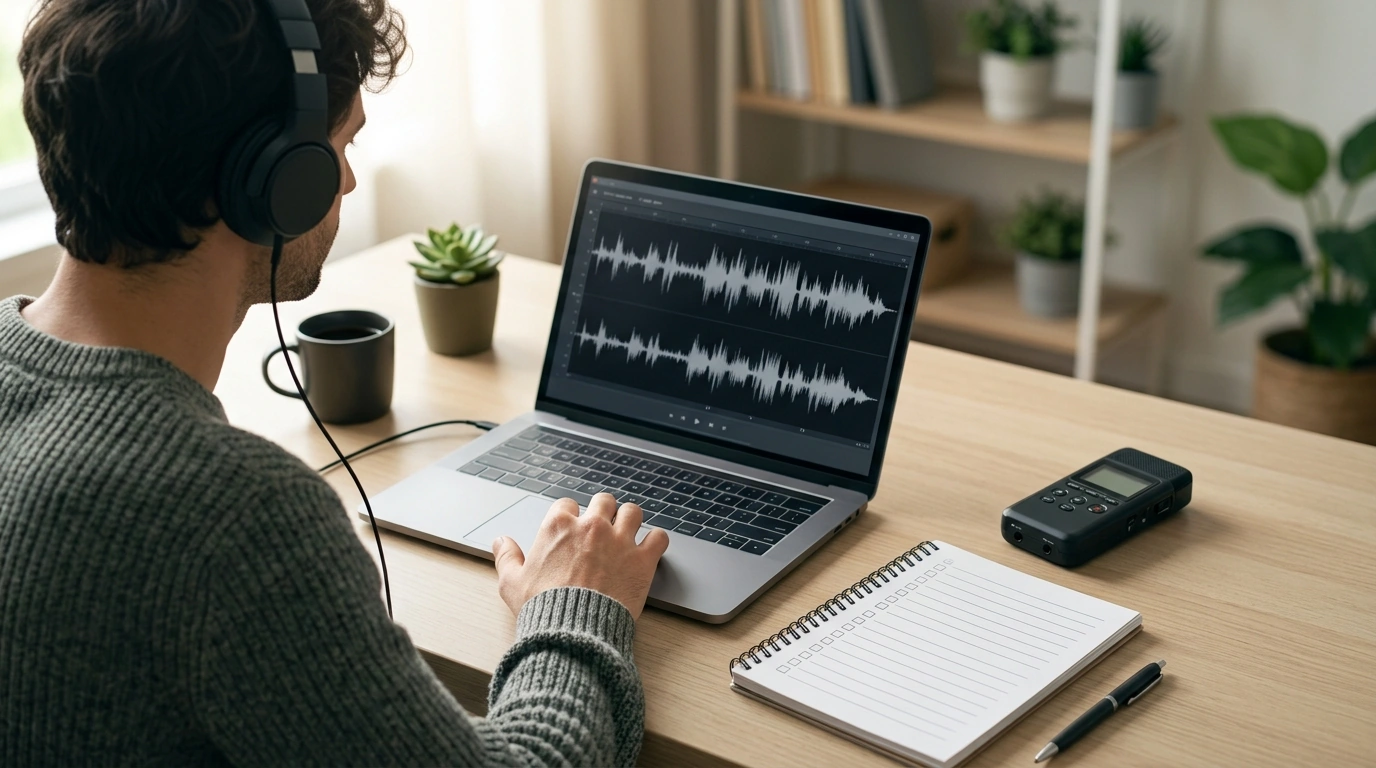
Transcribe Like a Pro with ChatGPT: A Checklist-Driven Workflow for Fast, Accurate Audio Transcription
Clean transcripts don’t happen by accident—they come from a repeatable workflow. Our team uses a checklist-first method to keep transcription fast, consistent, and easy to verify, whether you’re capturing meeting notes, interviews, lectures, podcasts, or research calls. The goal is simple: predictable steps that reduce errors, keep speaker turns clear, and make the final text immediately usable.
What “pro-level” transcription actually means
“Accurate” isn’t just getting most words right. A pro transcript is reliable enough that you can quote it, search it, and act on it without constantly second-guessing.
- Accuracy beyond words: correct names, numbers, acronyms, and domain terms.
- Structure that reads well: clean paragraphs, speaker labels, timestamps (when needed), and consistent formatting.
- Editing discipline: a quick verification loop for what typically breaks—proper nouns, dates, jargon, and links.
- Deliverables that match the use case: verbatim vs. clean read, plus optional summaries, action items, or captions.
Before transcribing: a 3-minute setup that prevents 30 minutes of cleanup
If you decide the rules after the transcript is “done,” you’ll spend your time reformatting instead of verifying. Set your standards first.
- Choose a transcript style: verbatim (includes false starts and filler) or clean (readable, minimal filler).
- Decide the output format: Google Doc-ready text, Markdown, or captions (SRT/VTT).
- List known speakers and spellings: names, roles, and any tricky pronunciations (phonetic notes help).
- Collect context terms: project names, product names, acronyms, and “must-not-miss” keywords.
- Plan chunking for long audio: 5–15 minutes per segment reduces drift and stabilizes speaker identification.
Quick setup choices and when to use them
| Choice | Best for | Result |
|---|---|---|
| Verbatim | Legal notes, research, sensitive quotations | Maximum fidelity; more editing time |
| Clean transcript | Meetings, podcasts, internal docs | Readable text; fewer fillers |
| Timestamps every 30–60s | Review, fact-checking, editing | Fast navigation back to audio |
| Speaker labels | Interviews, panels, meetings | Clear attribution and scannability |
| SRT/VTT captions | Video publishing, accessibility | Import-ready captions |
How to use ChatGPT to transcribe audio (the reliable workflow)
Our team sticks to a two-phase approach: get text out fast, then make it correct and consistent. This avoids spending too long polishing early segments only to change rules later.
- Convert audio to text input: if your current toolchain supports direct audio transcription, use it; otherwise run a dedicated speech-to-text pass first, then bring the rough text into ChatGPT for cleanup and formatting. (If you’re building a workflow, OpenAI’s Audio documentation is a solid reference.)
- Work in chunks: paste one segment at a time with clear boundaries like “Segment 2 (07:30–15:00).” Chunking reduces “style drift” and keeps speaker names stable.
- Lock formatting rules: define speaker label style, paragraph length, timestamp cadence, and whether you want filler words.
- Run a first pass: prioritize structure—speaker turns, paragraphs, and basic punctuation. Don’t overcorrect yet.
- Run a verification pass: focus only on high-risk items: names, numbers, dates, URLs, technical terms, and anything that could break downstream decisions.
- Merge segments: combine into one master transcript while preserving timestamps and speaker consistency.
- Produce deliverables: generate a summary, action items, and key quotes derived from the final transcript (without rewriting the transcript itself).
Prompt pack: copy/paste templates that keep results consistent
- Transcript template: define speaker format, timestamp rules, verbatim vs. clean, and how to mark cross-talk and unclear audio (example format: “[inaudible 12:43]”).
- Normalization template: standardize capitalization, numbers (like “$1,250”), dates, and units without changing meaning.
- Speaker consistency template: enforce a fixed list of speakers and rename mismatched labels (for example, unify “Host” and “Interviewer”).
- Accuracy audit template: request a checklist-style scan for likely error zones and mark uncertain words for human verification.
- Caption template: transform the transcript into SRT or WebVTT with readable line breaks and length limits. For caption formatting specifics, the W3C WebVTT standard is the authority.
Fix the problems that slow transcription down
Turn transcripts into assets: notes, posts, and documentation
The checklist that makes it repeatable (and faster every time)
Recommended tools from our store
- Transcribe Like a Pro with ChatGPT – Ultimate Checklist for Fast & Accurate Transcription | How to Use ChatGPT to Transcribe Audio (a ready-to-run workflow you can reuse across meetings, interviews, lectures, and podcasts).
- One Room, Real Progress: A Simple Step-by-Step Guide for Stress-Free Home Organization (a checklist mindset that pairs well with any repeatable process—great if you want your workspace and files to stay as organized as your transcripts).
- Maximize Function, Minimize Clutter | Multifunctional Room Layouts eBook | Small Space Design Guide (helpful when you’re setting up a dedicated recording/transcription corner and want it to stay functional).
FAQ
Should the transcript be verbatim or cleaned up?
Use verbatim when exact phrasing matters (legal notes, research, or sensitive quotations); use a clean transcript when readability and speed matter (meetings and podcasts). A simple rule: if you plan to quote it publicly, go verbatim; if you plan to scan and act on it, go clean. You can create both from the same rough transcript by applying different cleanup rules.
How do timestamps work if the transcript is produced in segments?
Label each segment with its true time range (for example, 00:00–07:30) and keep timestamps inside the segment consistent with the original audio. When you merge segments, preserve the existing timecodes and formatting so you can jump back to the exact moment for verification. Adding timestamps every 30–60 seconds makes review much faster.
What’s the fastest way to reduce name and jargon mistakes?
Start with a speaker list and a glossary (project names, acronyms, technical terms) and enforce it across every segment. Then run a focused accuracy check on proper nouns, acronyms, and numbers before you polish anything else. When something is unclear, flag it for manual verification rather than guessing.
Leave a comment